Releases on GitHub Read more
Curiosity Spark
An inference server for GGUF language models, written in C#. Point an OpenAI or Anthropic SDK at it, or Curiosity Studio, and the models run on your own machines.
What is Spark?
Spark loads GGUF model files and serves them through two HTTP APIs on one port. It places models on NVIDIA GPUs with CUDA 12 when it finds them, and otherwise on the CPU (x64 with AVX2 or AVX-512, and ARM64). Nothing leaves your machines.
- OpenAI compatible API:
GET /v1/models,POST /v1/chat/completions,POST /v1/completionsandPOST /v1/embeddings. - Anthropic compatible API:
POST /v1/messagesandPOST /v1/messages/count_tokens. - Both stream with server-sent events, and support tool calls, reasoning output, JSON mode and JSON schema, and stop sequences.
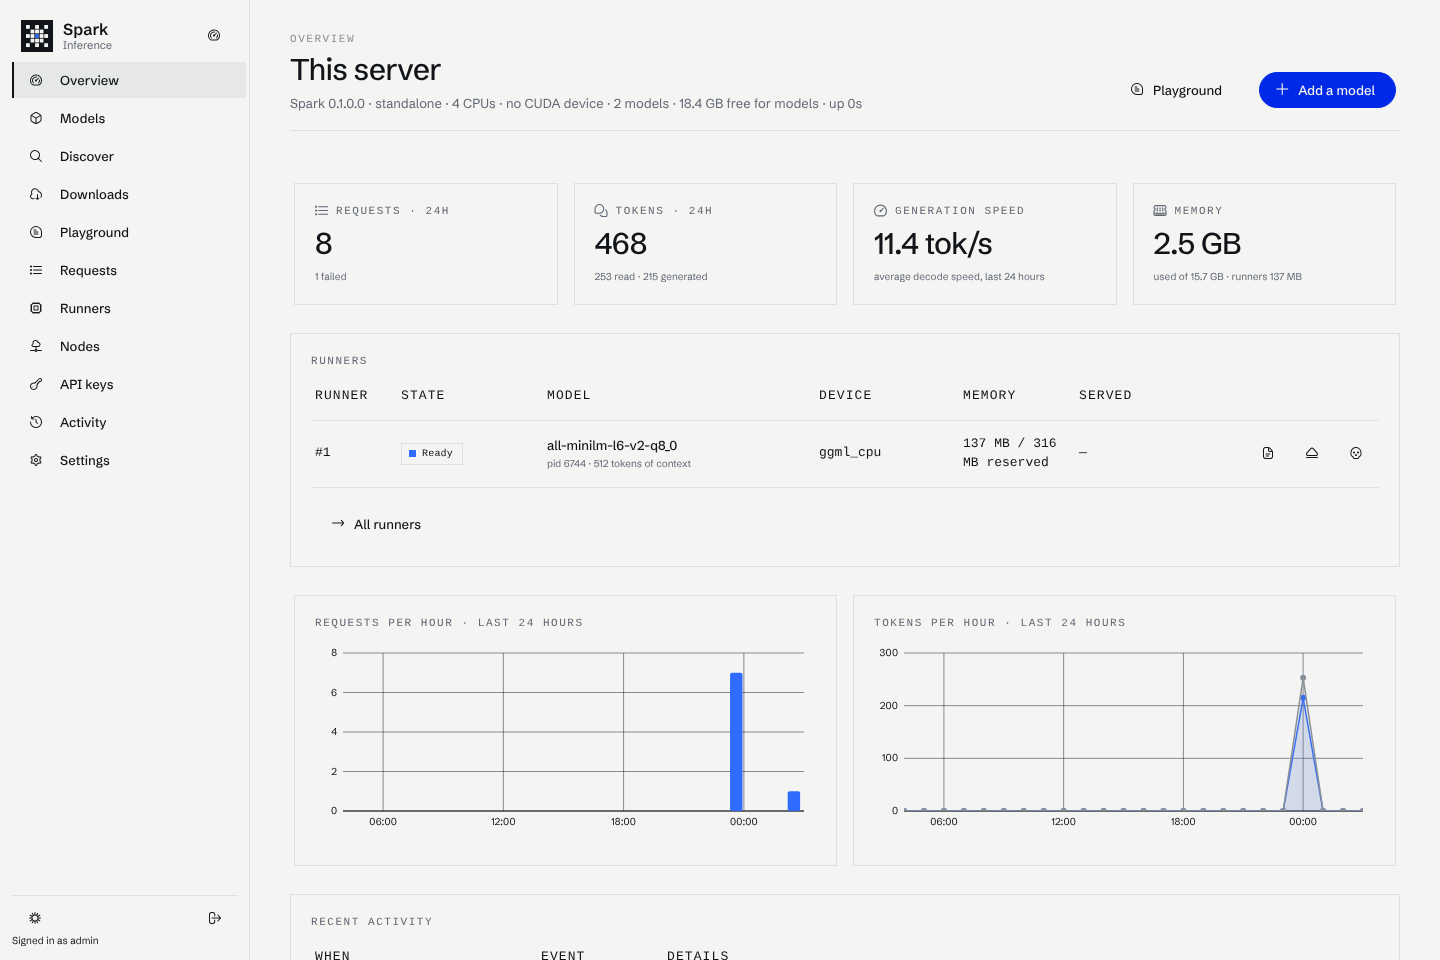
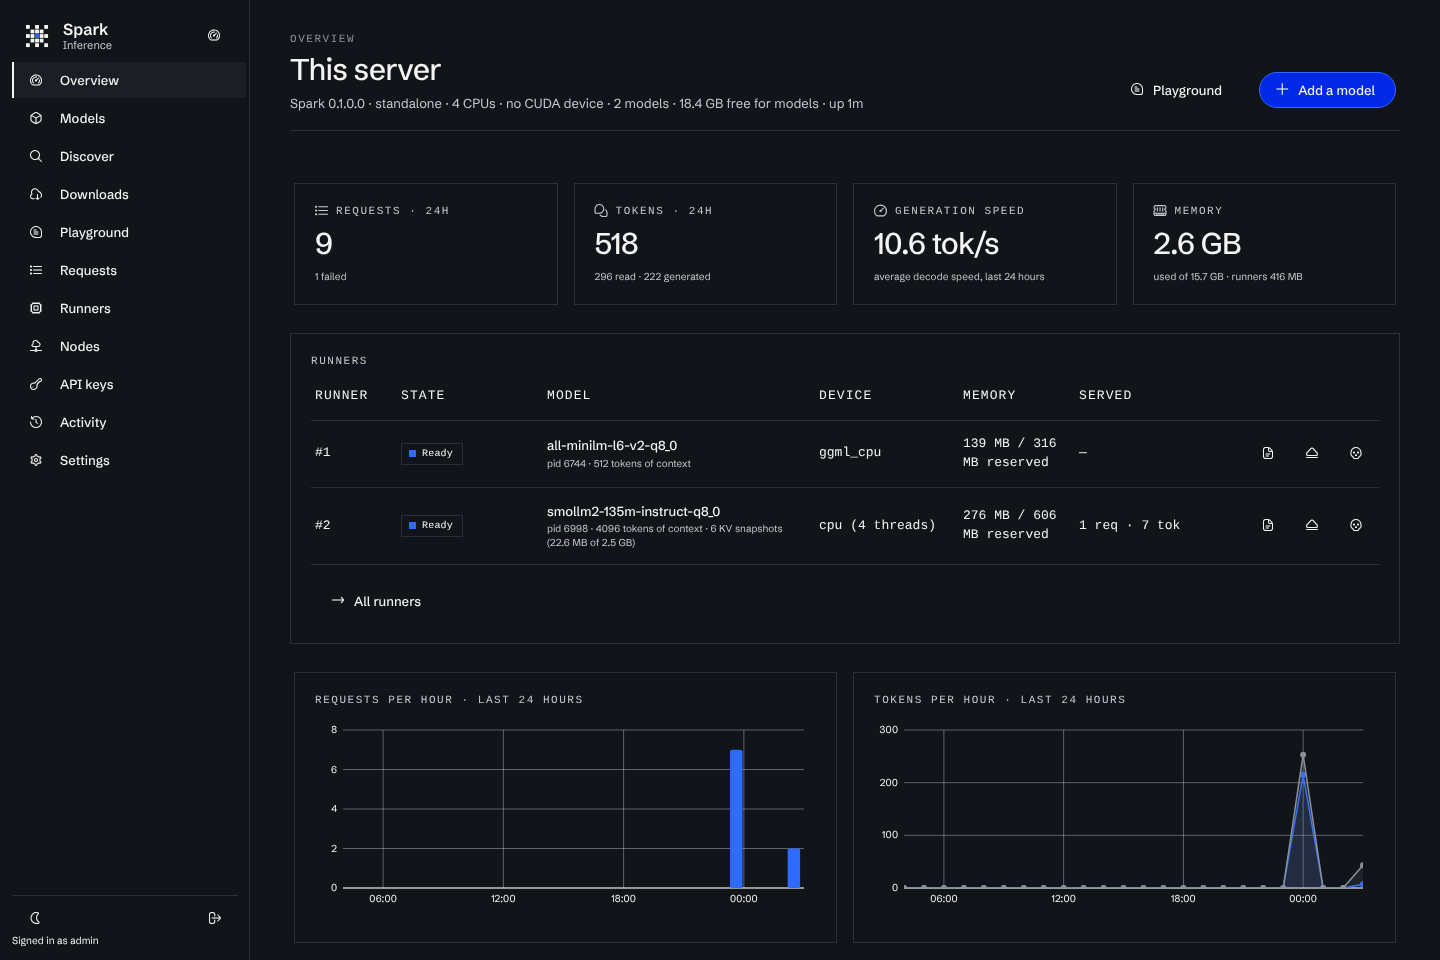
- A management console (
/, password protected) with the model library, Hugging Face search and download, runners, API keys, a playground, a request log with a timeline of every step, activity, settings and nodes. - Models run in separate processes. Each loaded model lives in a
spark-runnerchild process. A runner that crashes or hangs is restarted and its model reloaded, and the server keeps answering. - Placement by memory. Spark puts a model where its weights, KV cache and work buffers fit, unloads idle models to make room, and refuses a model that fits nowhere, with the arithmetic.
- Images and embeddings. A model with a vision projector reads images. Embedding models answer
/v1/embeddings. - KV cache that survives other conversations. The next turn of a chat reuses the live cache. A conversation pushed out by another is saved as a snapshot and restored when it returns.
- A fleet. A central Spark routes to models on nodes, other machines with other GPUs.
- Zero retention per API key. A key can be created so that its requests are logged without their content.
What it is not
- It does not batch requests. A runner answers one request at a time. Concurrent requests to one model queue in arrival order.
- It does not split one model across GPUs.
- It does not generate images, video or audio. Image and video generation families and audio input are not served.
- It is not the OpenAI API in full.
nabove 1,logprobs, the Responses API and file or audio content parts are not supported. See the compatibility matrix. - It does not terminate TLS. Put a reverse proxy in front for anything beyond your own network.
The five minute path
1
Install it
curl -fsSL https://raw.githubusercontent.com/curiosity-ai/spark/refs/heads/main/install.sh | sh
2
Start it
SPARK_ADMIN_PASSWORD='choose-a-password' spark
3
Add a model and a key
Open http://localhost:8080, sign in as admin, download a small model under Discover, then create a key under API keys.
4
Call it
curl http://localhost:8080/v1/chat/completions \
-H "Authorization: Bearer sk-spark-…" -H "Content-Type: application/json" \
-d '{"model": "smollm2-135m-instruct-q8_0", "messages": [{"role": "user", "content": "Hello!"}]}'
How it fits together
flowchart LR
C["Client: OpenAI or Anthropic SDK, Studio"] -->|"/v1/..."| S[spark server]
A[Administrator] -->|"console, /api/admin"| S
S --> R1[spark-runner: model A]
S --> R2[spark-runner: model B]
S -->|signed HTTP| N[spark node] --> R3[spark-runner: model C]
S --- DB[("models, keys, request log, nodes")]
Where to go next
- Settings: every
SPARK_*variable. - API compatibility: the parameters each endpoint reads.
- Troubleshooting: common failures and fixes.
- Spark on GitHub: the install scripts, the README and the releases.